Intelligent learning systems
 LurnIt
Adaptive mathematics learning for Singapore students.
Every attempt is read for the gap behind it — then the next question, hint and explanation are chosen to close that gap, from Primary 1 to Secondary 4.
ReLurn builds intelligent software that turns what happens into what to do next.
What you learn changes what happens next.
Each area runs the same loop — observe what happened, learn from it, change what happens next.
Intelligent learning systems
LurnItAdaptive mathematics learning for Singapore students.
Every attempt is read for the gap behind it — then the next question, hint and explanation are chosen to close that gap, from Primary 1 to Secondary 4.
Intelligent growth systems
AI-powered revenue and growth operations.
Search Console, GA4 and indexation signals read together — turned into a ranked action pipeline your team can ship from.
Intelligent decision systems
Turning complex information into better decisions.
Still an exploration, not a product: we are testing how far a system can go from observation to recommendation before anyone should rely on it.
Explore the direction →Every ReLurn product runs the same loop. Something happens — an answer, a visit, a decision. The system reads what actually happened, learns from it, changes what it does next, and then checks whether the change helped.
So the next attempt is better than the last one — for the student, for the team, and for the outcome.
Simplify 3/6 + 1/4.
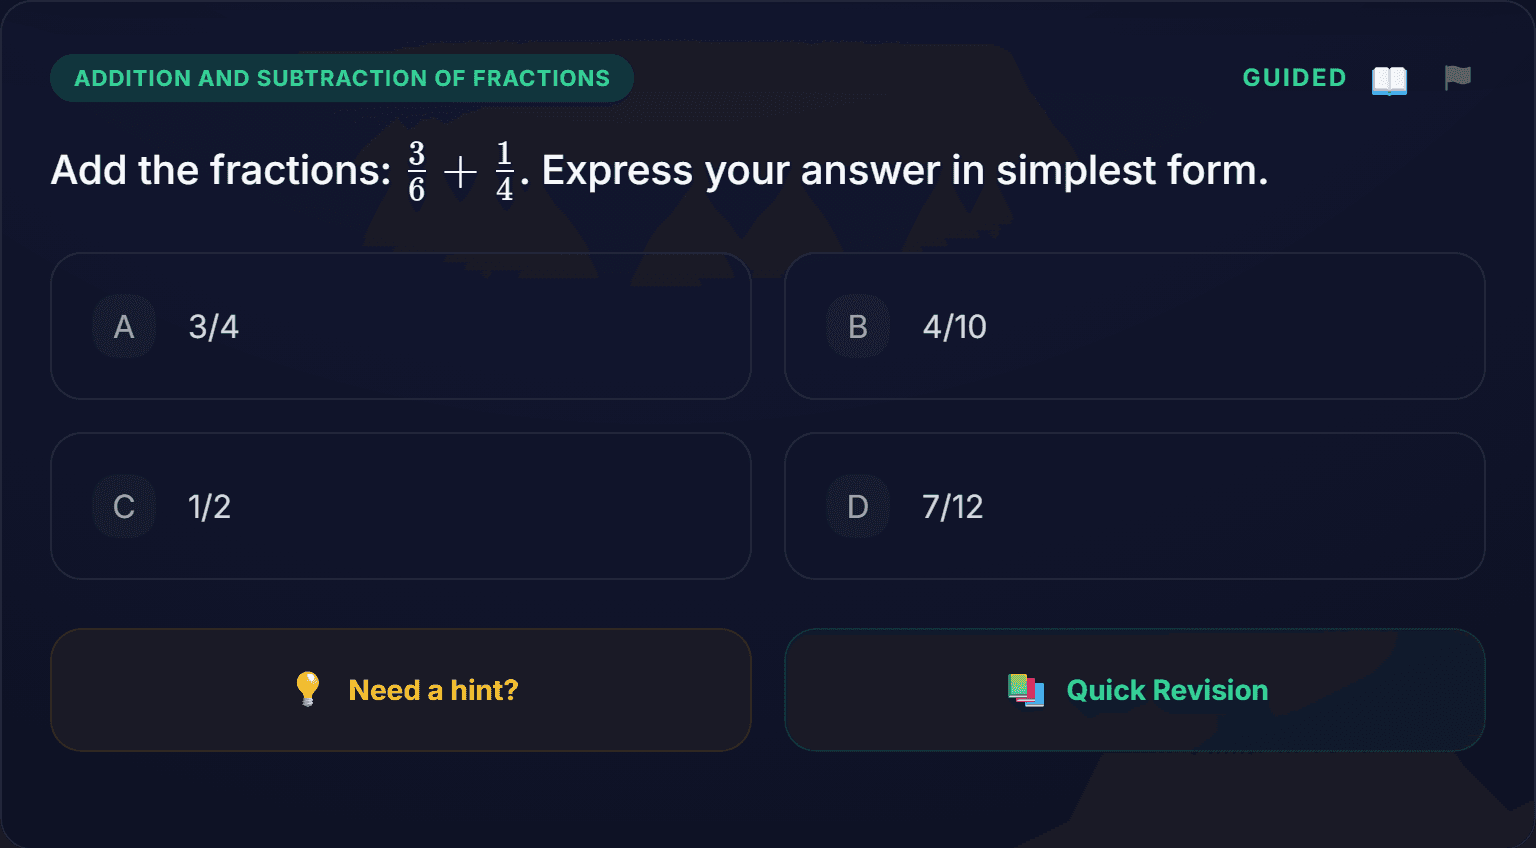
4/10 — the student adds straight across, top and bottom.
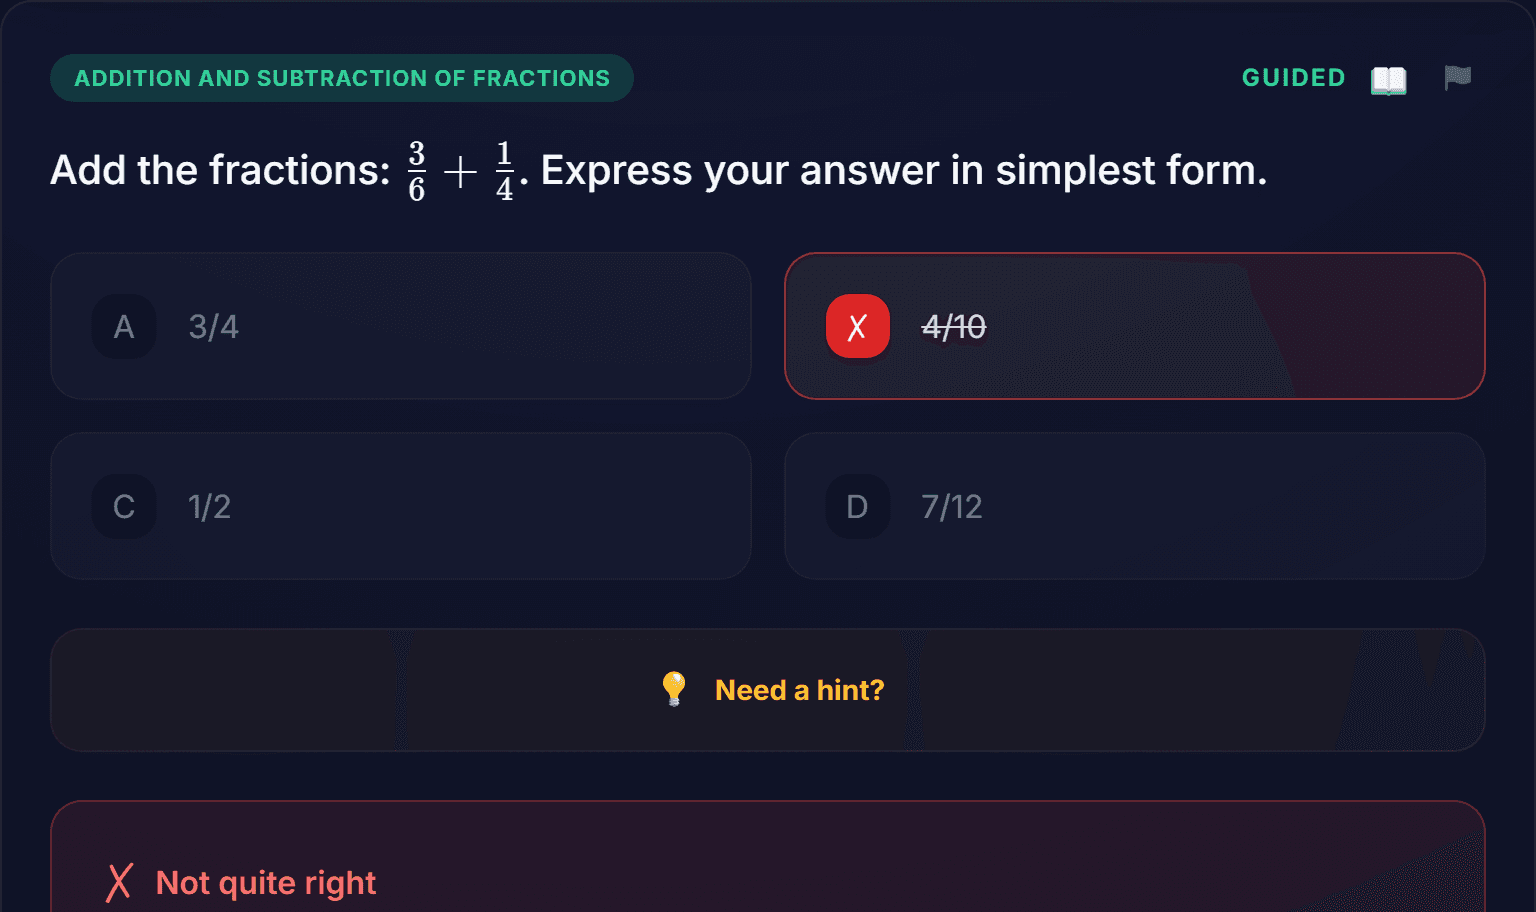
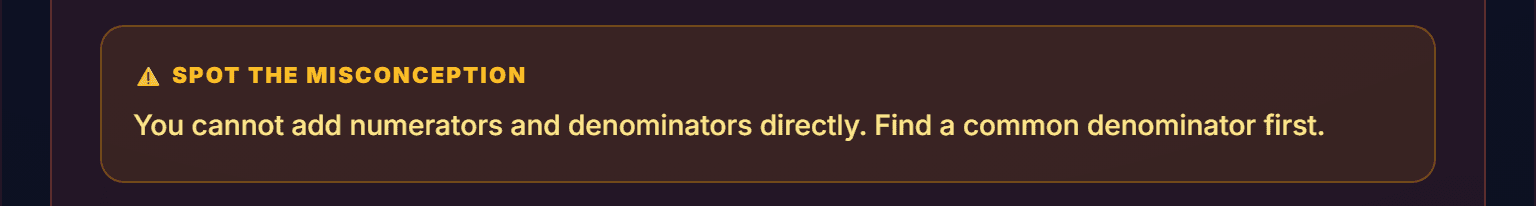
Not a slip: the rule for combining denominators was never understood, only memorised and lost.
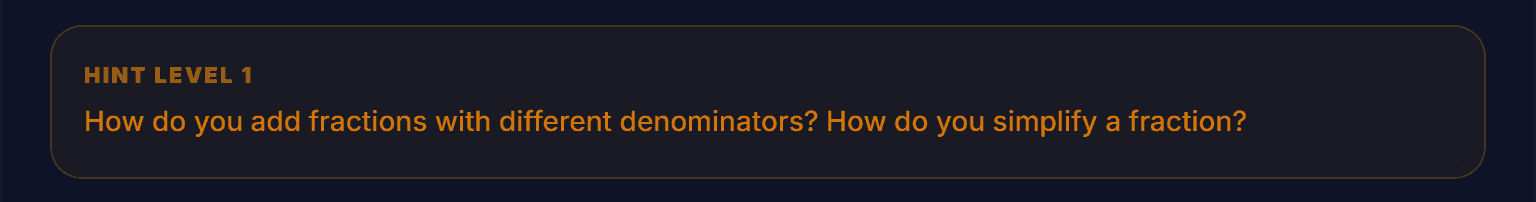
What would have to be true before these two fractions could be added? What is the denominator actually telling you?
Common denominator first: 6/12 + 3/12 = 9/12 → 3/4. Correct, and explained back.
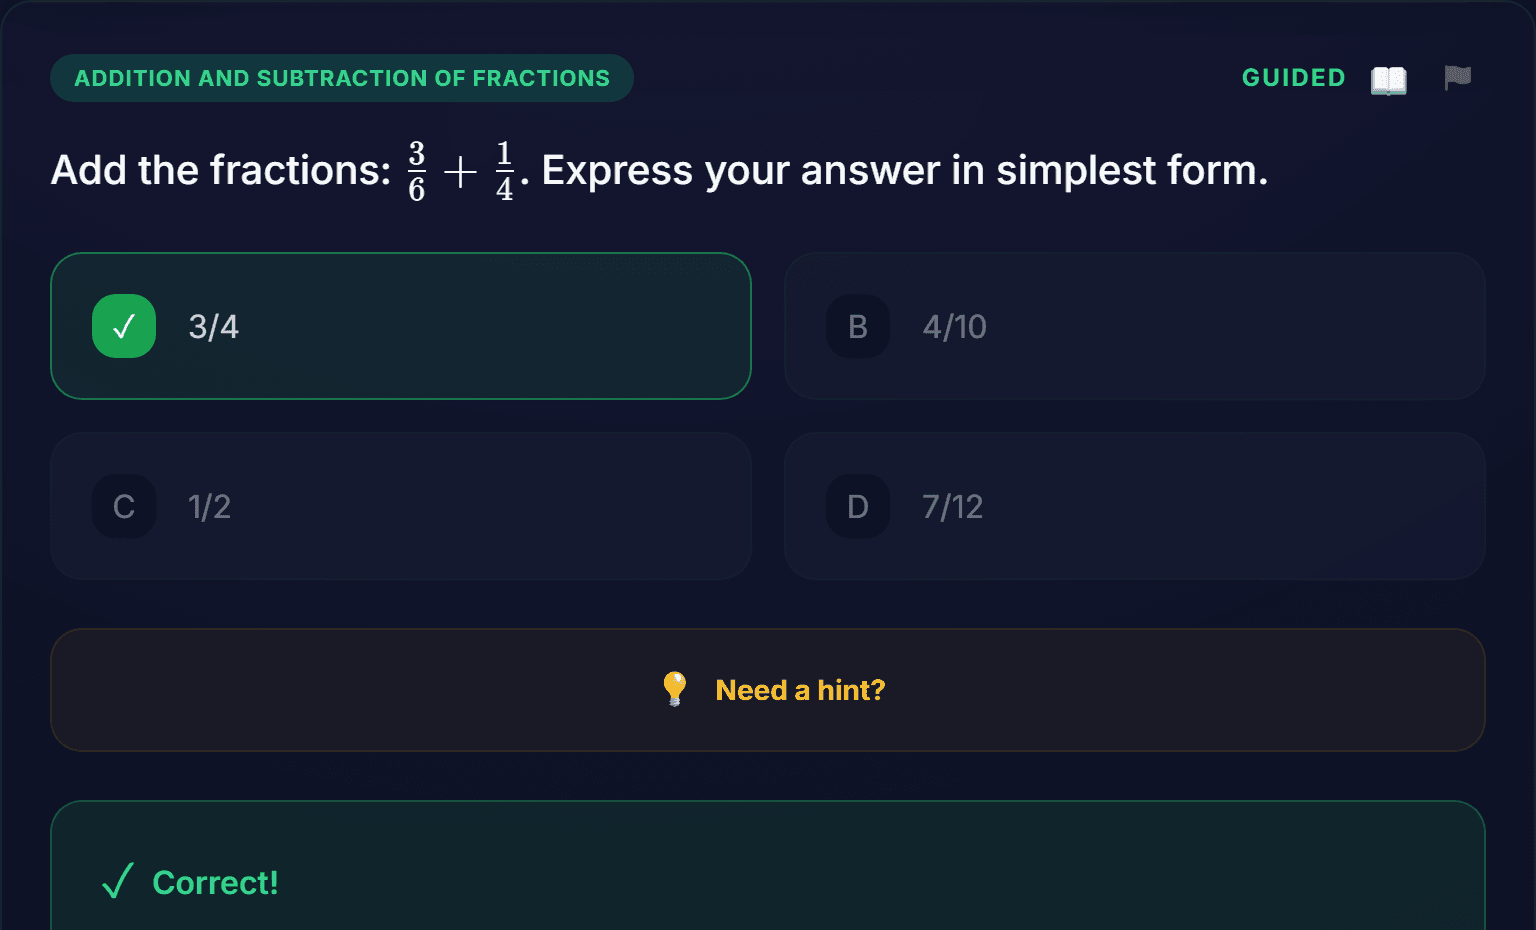
One wrong answer produced a rule the student can use on the next fifty questions.
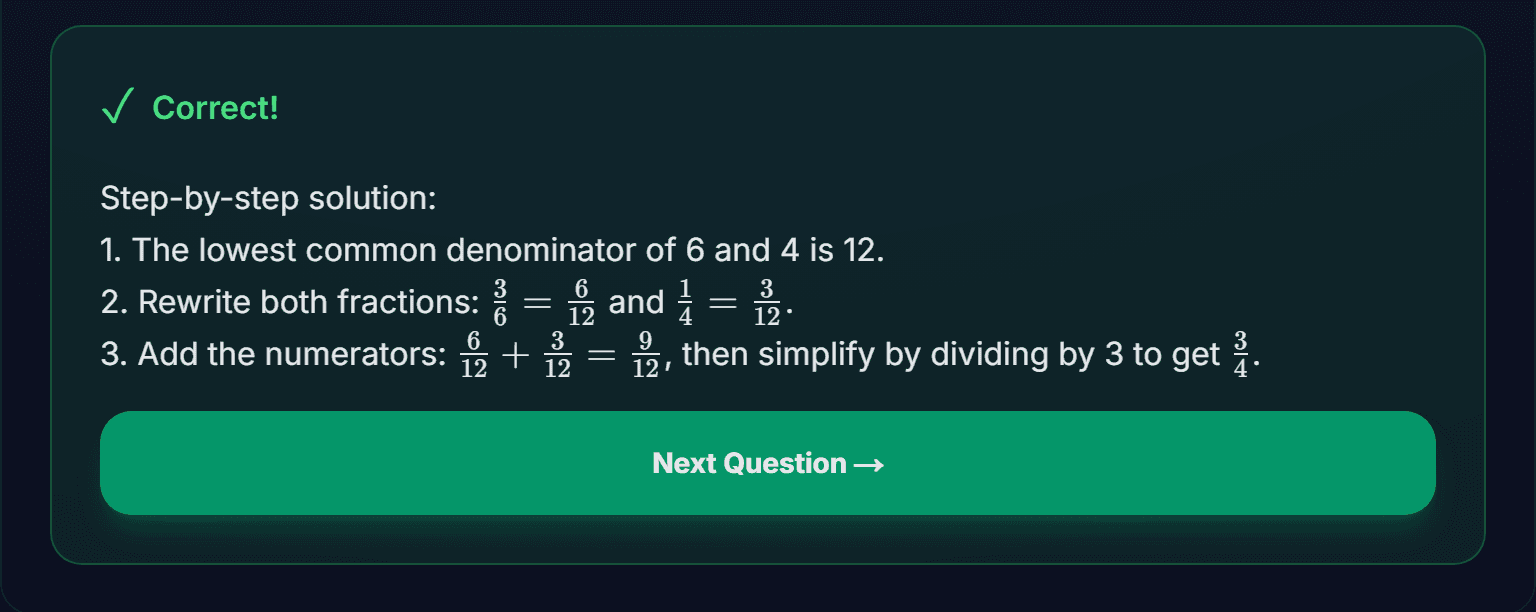
One mistake became information for the next attempt. This is the ReLurn principle.
LurnItNot built yet — so it does not appear on this list of proofs.
Each product runs the same loop in the open: it sees what happened, understands it, recommends the next move, acts — and shows what changed.
LurnItAutomating a task repeats what already happens. We build systems that change what happens next, because the last attempt taught them something.
A dashboard tells you what happened. We build software that explains why it happened — and what to do about it.
Insight that changes nothing is decoration. Our products act on what they learn: the next question, the next change, the next attempt.
The shipped mechanism — the feature that actually exists, not the roadmap intention.
The behaviour or outcome that moved once it was live, stated without spin.
The method, the window, and the artifact a sceptical reader could check.
Where we were wrong, what the evidence made us change, what we are testing next.
ReLurn builds intelligent software that turns what happens into what to do next — for students, for growth teams, and for the decisions in between.
ReLurn Intelligence is in development: an attempt to turn complex information into better decisions. We are still testing how far observation, reasoning and recommendation can go before anything should depend on them.
So it is not announced as a product and not promised as a date. When it can be used, it will appear — with the same evidence standard as everything else on this site.
What happens when software learns from what happens?